A conventional SSD performs a remarkably convincing trick. You ask it to replace a small piece of data, and it presents the operation as an ordinary update to a numbered storage location.
Inside the drive, the job can be more complicated: write the replacement elsewhere, update a mapping, and eventually move surviving data so old flash space can be erased and reused.
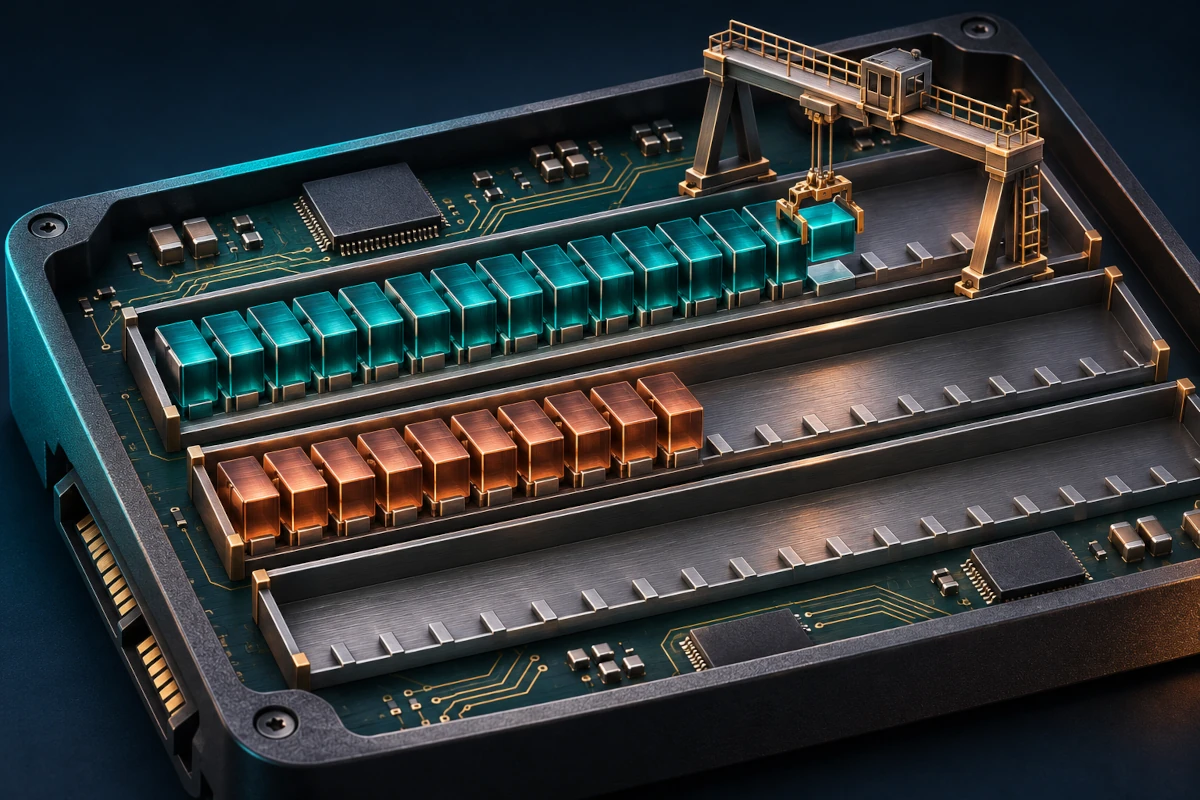
Zoned Namespaces propose a different agreement: let the software organize writes into sequential areas and explicitly recycle those areas when they are no longer needed. The SSD can spend less effort hiding an awkward relationship between the block interface and flash memory. [1][2]
The surprising part is that a stricter interface can make a well-designed storage system more efficient.
What Are NVMe Zoned Namespaces?
NVMe Zoned Namespaces, usually shortened to ZNS, divide a namespace’s logical address space into zones with sequential-write rules and explicit management operations. A namespace is a logical storage address space presented by an NVMe device. ZNS is a supported command-set capability, not a setting that turns every ordinary SSD into a zoned device. [1]
For someone familiar with ordinary PC storage, the rule sounds restrictive: why would a fast electronic drive object to where you write?
Because the neat array of replaceable logical blocks was always an abstraction.
Flash Has a Recycling Problem
NAND flash is programmed in pages and erased in larger blocks. Replacing a small logical record does not generally mean rewriting those same physical cells in place.
A conventional SSD’s flash translation layer maps logical addresses to physical storage. During garbage collection, valid data can be copied out of a block so that the block can be erased and reused. Those internal copies consume bandwidth and contribute to flash wear. [2][3]
The useful metric is write amplification: how much data reaches the flash compared with how much the host wrote.
For an invented example, suppose the host writes 4 GiB during an interval while the controller writes 10 GiB to NAND, including internal copying:
Device write amplification = NAND bytes written / host bytes written
                           = 10 GiB / 4 GiB
                           = 2.5
That is an illustrative calculation, not a benchmark. It also measures the device layer: a database may already have rewritten data through compaction before those writes reached the SSD.
ZNS creates an opportunity to coordinate placement and recycling across those layers, rather than leaving the drive to infer everything from unrelated block updates.
The Rule Is Per Zone, Not Per Drive
In the ordinary sequential-write model, each zone has a write pointer marking the next write position. Writing advances that pointer. Updating an earlier record means placing a new version elsewhere and having the software track which version is current. [4]
Imagine writing records A, B, and C into an empty zone. The next write goes after C. The application or storage layer can later write a replacement A and update its index, but it cannot treat the old A’s position as an ordinary freely rewritable slot.
Three distinctions matter:
- Reads can be random. You do not have to read A and B to reach C.
- The order applies within a zone. Different zones can support separate write streams; ZNS does not require one global append position for the whole SSD.
- Recycling is explicit. A zone reset returns the zone to an empty state for reuse, invalidating its previous contents. Live data must be preserved before resetting it. [4][5]
The standard also defines an optional Zone Random Write Area (ZRWA), which can permit out-of-order writes inside a bounded area under additional rules. The basic examples here assume that optional feature is not being used. It does not turn the entire namespace into unrestricted random-write storage. [5]
A Zone Is Not Just a Partition With a New Name
A disk partition divides a disk’s logical space for purposes such as volumes and file systems. A ZNS zone adds a different kind of contract: write ordering, state, and reuse rules.
| Question | Conventional block namespace | ZNS namespace, using its basic sequential model |
|---|---|---|
| Can the host replace an arbitrary logical block? | The block interface normally permits it; firmware manages the physical consequences. | Written positions cannot simply be overwritten in place. |
| Where does the next write go? | To the logical address requested by the host. | At the zone’s write pointer, or through an appropriate Zone Append operation. |
| Can existing data be read in arbitrary order? | Yes. | Yes; sequential writing does not imply sequential reading. |
| How is a zone made reusable? | No equivalent zone-management requirement in the conventional interface. | Reset the zone after its live contents are no longer needed or have been relocated. |
One detail can surprise software developers: zone size and zone capacity are different measurements. Size describes the zone’s logical-address range; capacity describes how many blocks in it can hold written user data. Capacity can be smaller than size, so software must inspect the reported capacity rather than assume every address in the range is writable. [6]
The Clever Part: Keep Data That Expires Together Together
Writing in order is only half the opportunity. Choosing what shares a zone can determine how expensive recycling becomes.
Consider two zones from a larger device. For this tiny teaching example, each holds eight equal-sized records. Eight records are short-lived; eight are long-lived. Eventually, all the short-lived records become obsolete.
| Placement | Contents before expiration | What remains afterward |
|---|---|---|
| Mixed lifetimes | Each zone contains four short-lived and four long-lived records. | Each zone still holds four live records. Reclaiming either whole zone requires preserving those survivors elsewhere. |
| Grouped lifetimes | One zone contains eight short-lived records; the other contains eight long-lived records. | The short-lived zone has no live records. It can be reset and reused without copying survivors from it. |
Both layouts stored sixteen records. Both lost eight obsolete records. The difference is whether the remaining data prevents a whole zone from becoming reusable.
The eight-record capacity is fictional, and this snapshot is not an endurance or performance estimate. Real software also has to handle imperfect lifetime predictions, partially filled zones, and changing workloads.
The principle has a concrete implementation: ZenFS, a RocksDB storage backend, uses write-lifetime hints to co-locate files with similar expected lifetimes. [7]
“Write in order” is therefore less interesting than “make future recycling cheaper.”
Zone Append Helps With Concurrent Writers
Several writes in flight create another problem: the order in which software submits them is not necessarily the order in which the controller processes them.
Zone Append lets the host identify the target zone while the controller chooses the write location and reports the starting logical block address in the completion. Software must record that returned location. [5]
It is not a promise that concurrent appends preserve application submission order. An application needing its own record order or transaction guarantees still has to implement them.
Resource limits also matter. A controller can limit how many zones are open, and separately how many are active. Active includes open and closed zones. Closing a partly written zone does not reset it or necessarily release an active-zone resource. [6]
These are scheduling constraints for the storage stack, not reasons to abandon parallelism altogether.
The Host Does Not Become a Raw-NAND Controller
Giving software more placement responsibility does not transfer every SSD job to the operating system.
NVM Express explicitly explains that a ZNS SSD retains an FTL and manages media-specific behavior internally. The host is not expected to take over NAND reliability management. [8]
A zone is a logical management unit. Treating it as a literal, universally fixed diagram of one physical flash erase block would mistake the interface for the implementation.
The software gains a clearer agreement about writing and recycling. The device still has important work behind that agreement.
Which Software Handles the New Rules?
Some layer must turn application activity into valid zoned operations. It can be a storage engine, a specialized backend, or a file system.
For context, a general file system such as NTFS organizes files and metadata above a device interface. ZNS changes the contract underneath that layer; familiar file operations do not automatically establish compatibility with a zoned namespace.
Two Linux approaches illustrate the choices:
- zonefs exposes zones as files and keeps their sequential-write constraints visible to the application. It is deliberately simpler than a general-purpose POSIX file system. [9]
- Zoned XFS handles zoned storage through a general-purpose file-system approach. Support arrived with Linux 6.15, allowing applications to benefit from a compatible file-system layer without each implementing raw zone management. Its documentation still describes the support as experimental and specifies version, layout, and feature limitations. [10]
For ZNS devices without conventional writable zones, the documented XFS arrangement requires separate randomly writable storage for metadata. That is a system-design consideration, not merely a different formatting label. [10]
The question is therefore where to place the adaptation—and what that layer costs.
What Does the Stricter Contract Actually Buy?
Potential gains include less device-side copying, lower mapping-memory requirements, and more predictable latency under suitable workloads. The USENIX ATC 2021 ZNS paper demonstrated benefits using zone-aware f2fs and RocksDB configurations in controlled comparisons. Those results establish an opportunity, not a universal speed multiplier. [11]
Host-side relocation, database compaction, metadata, and recovery do not disappear because the interface becomes zoned. A system can reduce one layer’s amplification while still doing substantial work elsewhere.
When evaluating a design, examine:
- Sustained behavior: throughput and tail latency after the initial empty-drive phase.
- The complete write path: application rewrites, host relocation, and device-level writes where telemetry is available.
- Reclamation: whether the software maintains enough reusable zones as data ages.
- Integration: memory, CPU, recovery behavior, and compatibility with the actual software stack.
These measurements are more informative than assuming that sequential placement guarantees better results for every workload.
Order Is a Way to Share Responsibility
NVMe Zoned Namespaces make part of the storage contract more explicit. Software that knows which data belongs together can use that knowledge to shape writes and make space reusable with less unnecessary movement.
The SSD has not become a tape drive, and the host has not become its flash controller. They have agreed on a different division of work.
Sometimes the route to a better storage system begins with the drive asking one reasonable question: could you put the next thing after the last thing—and tell me when the whole area can be used again?
References and Further Reading
- NVM Express: Zoned Namespaces Command Set Overview and Specifications.
- NVM Express: New NVMe Specification Defines Zoned Namespaces—flash constraints and the conventional block interface.
- KIOXIA: How Does Endurance Work in SSDs?—garbage collection and write amplification.
- Zoned Storage: Zoned Storage Devices—write pointers and the zoned model.
- NVM Express Zoned Namespace Command Set Specification, Revision 1.5, ratified July 31, 2026—Zone Append, reset, and the optional ZRWA feature.
- Zoned Storage: SSDs With NVMe Zoned Namespace Support—zone capacity and resource limits.
- ZenFS: RocksDB Storage Backend for ZNS SSDs and SMR HDDs—lifetime-based placement.
- NVM Express: NVMe 2.0 Webinar Questions and Answers—the FTL and media-management boundary.
- Linux Kernel Documentation: zonefs.
- Zoned Storage: XFS—requirements, implementation, and limitations.
- Bjørling et al., ZNS: Avoiding the Block Interface Tax for Flash-Based SSDs, USENIX ATC 2021.