
The Editorial Team is a collective of technology enthusiasts, computer network engineers, and industry professionals dedicated to creating meticulously curated content for a diverse readership. With a combined experience spanning several decades, our team distills complex technology topics into clear, informative articles. Whether it’s networking fundamentals, cutting-edge AI insights, or in-depth guides on blockchain technology, the Editorial Team strives to provide reliable information that advances the understanding of technology for everyone from students to seasoned professionals.
Editorial Team’s mission
The Editorial Team’s mission extends beyond mere reporting; we aim to be the architects of understanding, constructing bridges over the rivers of jargon and complexity. From the foundational bricks of networking to the ever-evolving skies of cloud computing, we guide you through the technological labyrinth.
We take pride in our meticulous attention to detail and our unwavering commitment to accuracy, ensuring that each piece of information is a thread in the vast tapestry of technological knowledge. As we chart the course through the evolving landscape of technology, we invite our readers to join us on this exhilarating journey of discovery and growth. Together, we not only explore the current terrain of technology but also anticipate the horizons of tomorrow’s innovations.
Our Latest Articles
-
Python asyncio: How to Do More While Waiting
Four slow services do not have to make your program wait four times in a row. Explore Python asyncio with a runnable parcel-dashboard simulation, then add concurrency limits and timeouts. Learn what async and await really do—and why blocking code can make the whole event loop stand still.
-
CXL Memory Pooling: What Happens When RAM Escapes the Server?
One server runs out of RAM while another leaves memory idle. CXL memory pooling offers a different arrangement: capacity allocated from a separate resource. Discover how it works, how pooling differs from sharing, and why latency, software, and workload timing determine whether the idea pays off.
-
Why Ethernet Cables Get Warm: The Hidden Engineering of PoE
PoE turns an Ethernet cable into a power circuit as well as a data link. Discover why current produces heat, how bundles change the temperature rise, and why conductor size, resistance balance, and installation conditions matter as much as the switch’s wattage rating.
-
Shamir’s Secret Sharing: How to Split a Secret Without Revealing It
Any three shares can recover the key, while two reveal no secret-value information under the scheme’s assumptions. Discover how Shamir’s Secret Sharing works through a tiny numerical example, a Python check, and the practical limits of distributed custody.
-
Ethernet vs. Token Ring: How the LAN Wars Were Won
Token Ring gave computers permission to speak. Ethernet let them contend—then changed the rules. Discover how switches, full duplex, faster links, and a thriving supplier ecosystem decided the LAN wars.
-
KV Cache: The Memory Trick That Makes AI Conversations Faster
very new AI token needs earlier context. KV cache saves reusable attention calculations instead of rebuilding them—but the memory bill grows. Discover prefill, decoding, prefix reuse, and a worked example where one sequence needs 2 GiB of cache.
-
Happy Eyeballs: The Invisible Race That Gets You Online Faster
A website can have several addresses, and one slow connection attempt should not hold everything up. Discover how Happy Eyeballs coordinates IPv6 and IPv4 attempts to reduce delays—and how to investigate each address family separately.
-
Bandwidth-Delay Product: The Invisible Cargo in Your Network
A fast network needs enough data in flight to keep working at full capacity. Discover how bandwidth-delay product connects bandwidth, round-trip time, and TCP windows—with worked examples explaining why a gigabit path can still deliver a surprisingly slow transfer.
-
CYCLADES: The French Network That Made Failure Part of the Plan
A French research network asked a radical question in the 1970s: who should recover when a packet disappears? CYCLADES helped put the answer at the endpoints.
-
The Haunted Python List: Why One Edit Changes Every Row
Change one cell in a Python board and three rows change. Solve the mystery of shared lists with seven tiny experiments, then discover why even deepcopy keeps a surprising secret.
-
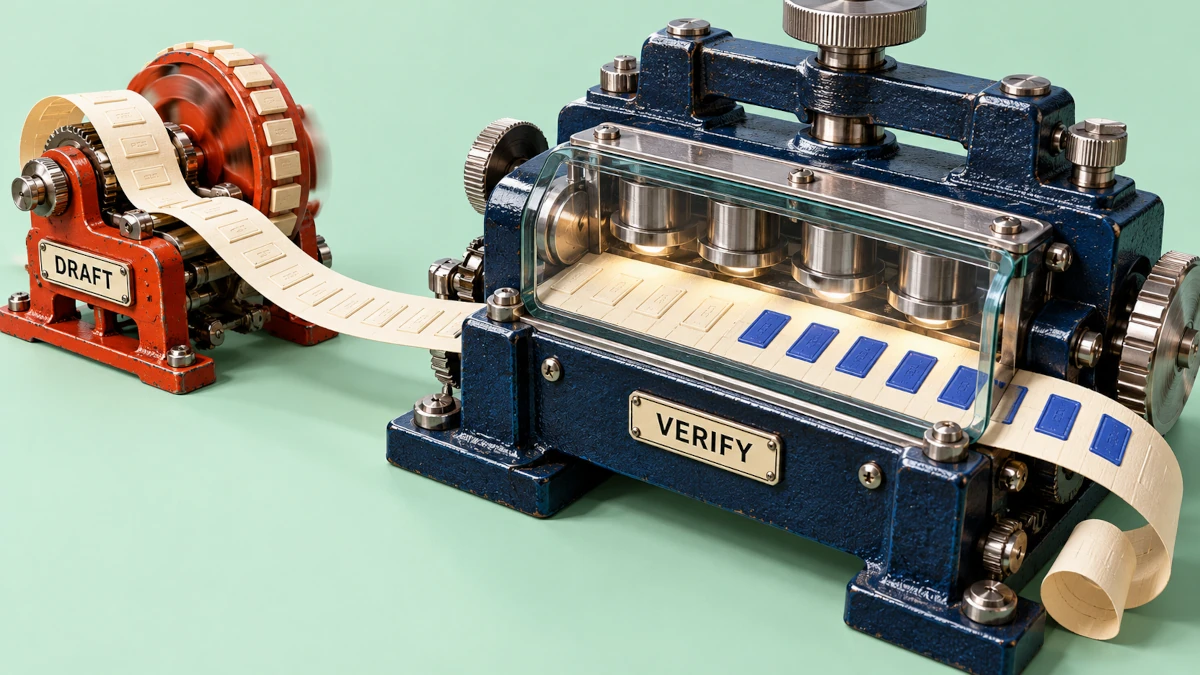
Speculative Decoding: How a Smaller AI Makes a Bigger One Faster
A small AI drafts ahead while a larger model checks several tokens together. Discover the probability trick that can accelerate generation without changing the target distribution.